Ollama: run an LLM locally without paid APIs (2026 guide)
My AI API bill kept climbing month after month, driven by tasks I almost felt ashamed of: summarizing monitoring articles, classifying hundreds of keywords, pre-sorting raw notes. Paying premium prices for that was like renting a Ferrari to buy bread.
Ollama solves this precise problem: a free local LLM, installed in five minutes, running on an ordinary machine and soaking up bulk tasks. Here is the hardware you actually need, the step-by-step installation, my daily use cases and the honest limits of the exercise.
✨ Key Takeaways
- Ollama installs and runs open source models locally, with no subscription and no data sent to a cloud.
- A computer with 8 GB of RAM is enough for compact models; a GPU with 8 GB of VRAM makes interactive use smooth.
- The installation boils down to one command on Linux and macOS, one graphical installer on Windows.
- The right use cases: summaries, classification, sensitive data, processed in batches through the local API.
- High-end creative writing remains the territory of large cloud models: better to embrace the complementarity.
After several weeks of mixed use, my rule is simple: volume and confidential work locally, writing and complex reasoning in the cloud. My API spending line went down, my productivity did not budge. That is the real verdict of this Ollama tutorial.
The hardware you really need (and the one they sell you for nothing)
Marketing videos promise local LLMs on a 50-euro nano-computer. Technically true, practically painful. Here is the realistic grid I use when advising the entrepreneurs I work with:
| Setup | What it looks like in practice | Recommended models |
|---|---|---|
| 8 GB of RAM, no GPU | It runs, slowly. Fine for overnight batch jobs | 3B models like llama3.2:3b |
| 16 GB of RAM | Comfort zone for everyday use | Quantized 7B-8B models like llama3.1:8b, mistral |
| GPU with 8 GB of VRAM, or a 16 GB Apple Silicon Mac | Fast answers, pleasant conversation | 8B models, even compressed 13B ones |
| GPU with 24 GB of VRAM or more | Territory of heavyweight local models | 30B models and up |
Three landmarks to find your way through this vocabulary. The number followed by B indicates billions of parameters, roughly the model’s capability. Models offered by Ollama are quantized, meaning compressed to fit your machine’s memory. And a quantized 8B model takes up about 5 GB on disk: plan storage space and just as much free RAM at runtime.
My cruising setup: a laptop with 16 GB of RAM and no dedicated GPU. Answers come at speed-reading pace, more than enough for batch jobs launched before lunch. For long interactive conversations, I switch to my cloud subscriptions, without second thoughts.
Ollama installation: step by step on all three systems
Head over to ollama.com, Download section, then follow your platform’s path.
On Linux, a single line does it:
“`bash
curl -fsSL https://ollama.com/install.sh | sh
“`
On macOS with Homebrew:
“`bash
brew install ollama
“`
On Windows, download the graphical installer from the official website and double-click. That is all.
Then check that everything breathes properly:
“`bash
ollama –version
“`
Then download and run your first model:
“`bash
ollama pull llama3.2:3b
ollama run llama3.2:3b
“`
The first command downloads the model, a few minutes depending on your connection. The second opens a chat session right in the terminal: type your question, chat, then exit cleanly with `/bye`. Two handy commands to keep the big picture:
“`bash
ollama list
ollama ps
“`
A practical note from my Ollama installation on three different machines: the app runs in the background after installation on macOS and Windows, and the service starts automatically on Linux. If you prefer a graphical interface, third-party apps like Open WebUI plug into Ollama, but the terminal remains the most direct path to start.
Three solopreneur use cases that pay for the beast
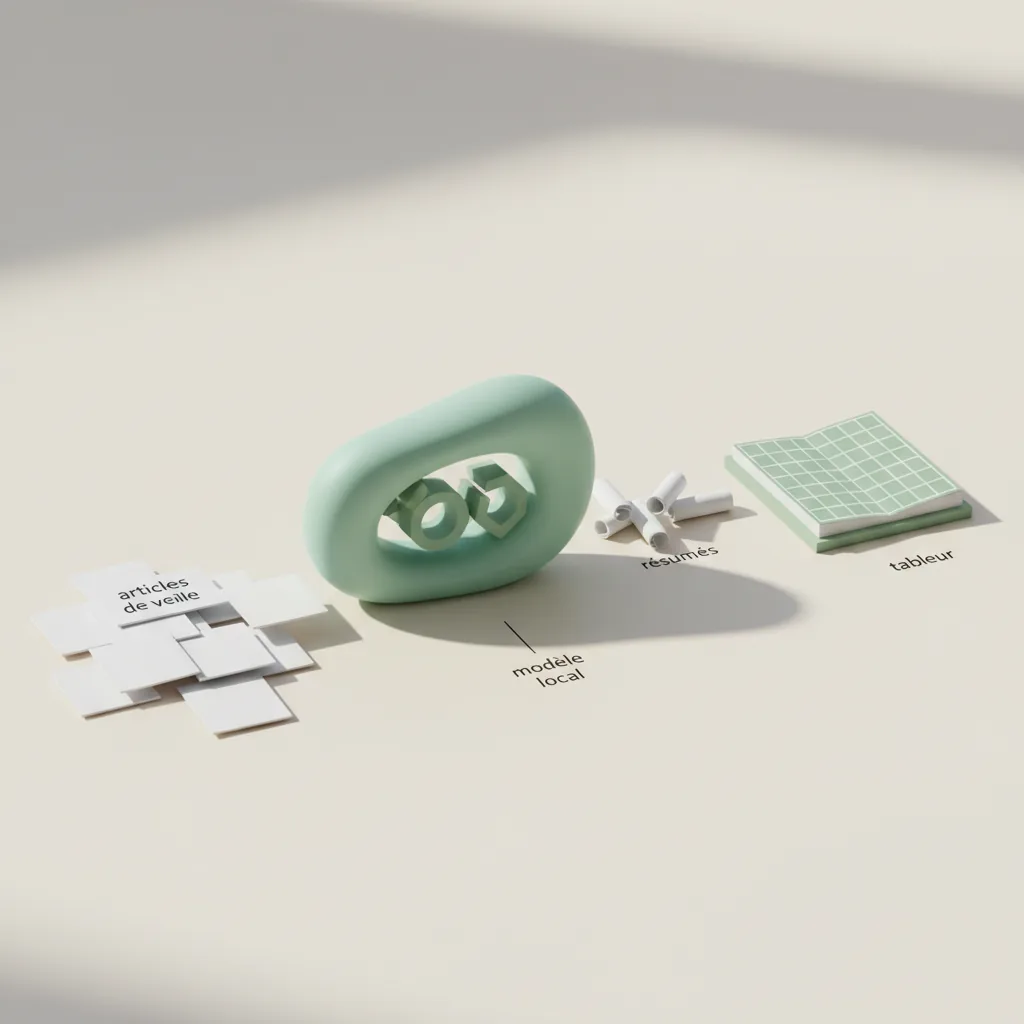
Case number 1: monitoring summaries. Every week I collect articles and newsletters in a dedicated folder. A small Python script sends each text to Ollama’s local API and returns three factual bullets per article. I read forty summarized sources over my morning coffee, without spending a cent on APIs.
The local API speaks HTTP, so any scripting language can connect to it:
“`bash
curl http://localhost:11434/api/generate -d ‘{
“model”: “llama3.2:3b”,
“prompt”: “Summarize this text in 3 factual points: [your text here]”,
“stream”: false
}’
“`
Case number 2: classification at scale. Tagging 500 SEO query lines by intent — informational, commercial or transactional — is the perfect chore for a 3B model. The result then feeds my clustering spreadsheet. For the full scripting method, I detailed my Python micro-automations in a dedicated article.
Case number 3: sensitive data. Personal notes, revenue figures, strategic drafts: everything I refuse to send to a third-party host goes through my local AI model. Nothing leaves the machine, and internet access is not even needed anymore once the models are downloaded.
A bonus flowing from the previous ones: plugging Ollama into a visual automation tool like n8n opens the door to hybrid workflows, half local, half cloud. I dedicated an n8n guide designed for solopreneurs to it if you want to see the complete chain.
Limits: where the cloud keeps the edge
Limit number 1: the pen. A local 8B model writes a decent summary and an average LinkedIn post. For in-depth writing in flawless French, large cloud-hosted models keep a clear lead. So I do all the final writing on the cloud side, and the preprocessing locally.
Limit number 2: raw speed. Without a GPU, a big 30B-and-up model becomes painful in interactive conversation. Overnight batch processing stays perfectly viable, real-time exchange does not.
Limit number 3: frozen knowledge. A local AI model knows nothing past its training date and does not browse the web on its own. It summarizes and transforms what you feed it; it does not go looking for missing information on your behalf.
Limit number 4: the context window. Many local models accept shorter contexts than top-end APIs. Documents several hundred pages long remain easier to digest on the cloud services side.
None of these limits is disqualifying if you place the tool on the right floor of the house. Ollama is the volume worker, not the writing star. A free local LLM excels exactly where APIs cost a lot for little.
Final word
A free local LLM does not replace your cloud subscription, it absorbs what deserves to stay home: repetitive volume and confidential material. Install Ollama tonight, download a 3B model, have it summarize three monitoring articles. If the pace suits you, you just trimmed a fixed-cost line without losing capability.
My other field experiments, tested hardware and full scripts, are gathered in the Lab section.
FAQ: frequently asked questions about Ollama
Is Ollama really free?
Yes. Ollama is open source software and the models it downloads are published under open licenses. You only pay for the electricity consumed by your own machine.
What is the difference between a 3B model and a 70B model?
The number expresses the model’s billions of parameters. The higher it is, the more capable the model, but the more RAM or VRAM it demands and the slower it answers. For summarizing and classifying, a 3B to 8B model is more than enough.
Can you use Ollama without an internet connection?
Yes, once the models are downloaded. It is one of its major strengths: your data stays on the machine and the tool works fully offline, handy when traveling or on an unstable connection.
Does Ollama replace ChatGPT or Claude?
No, and that is not its role. It excels at volume and confidentiality tasks, not at high-level creative writing or very complex reasoning. The two approaches complement rather than oppose each other.
Which model should you start with?
Start with a versatile compact model like llama3.2:3b. If your machine has headroom, move up to an 8B model such as llama3.1:8b or mistral for better French language quality.

Leave a Reply